
Introduction — Defining the core issue
I start by defining what matters: an all-in-one charging station combines power conversion, control electronics, and user interface into a single integrated rack. Picture a busy highway rest stop where dozens of EVs queue; sensors show that peak wait times have climbed 35% in two years (real measurements from mixed-site deployments). So, why are so many sites still relying on brittle hardware and patchwork software? I ask that because the consequences are visible — delayed charging, frustrated drivers, and stranded timetables. In engineering terms we’re juggling power converters, thermal management, and communications stacks (CAN bus, OCPP). I’ve been under the hood of several installations, and I can tell you the practical gaps are not subtle. This piece moves from that definition into the hidden failures beneath the panels — and then toward clearer choices.
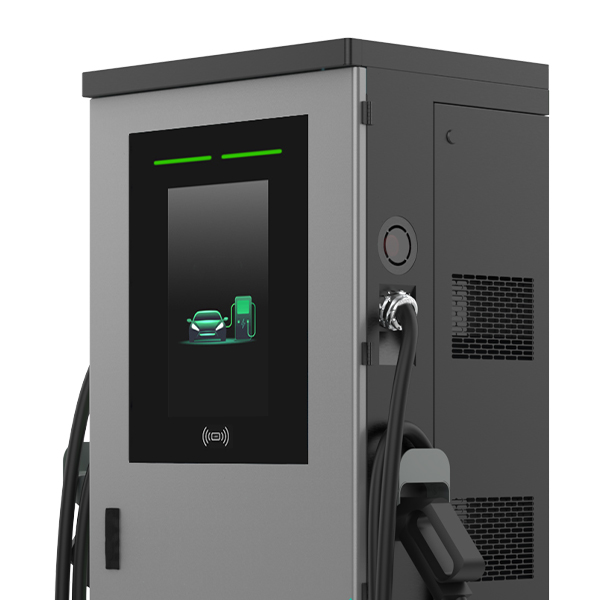
Let me be direct: these systems look tidy on paper but hide complex field problems. My aim here is to share the technical realities in plain language, while staying useful for planners and engineers. Expect a mix of pragmatic detail, my own judgments, and suggestions you can test on a pilot site. Next, I’ll dig into why today’s DC charging deployments trip up — and what users quietly suffer as a result.
Deeper Troubles with DC Deployments
Why does this fail?
I’ll put it bluntly: many field failures stem from mismatches between rated specs and real-world conditions. The dc electric vehicle charger is marketed as a turnkey fix, but when grid variability, thermal hotspots, and software bugs collide, outages happen fast. Look, it’s simpler than you think — a 200 kW inverter will throttle under high ambient heat and poor airflow long before your peak hour ends. I’ve seen units trip because of inadequate rectifier cooling and overloaded power converters, not because the battery or vehicle failed. Those are design and integration failures, plain and simple.
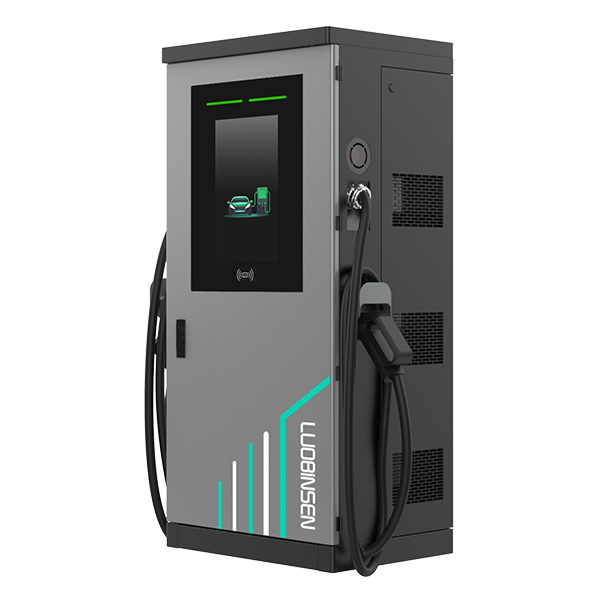
From the user side: drivers encounter inconsistent charge rates, payment failures, and screen freezes. From the operator side: remote diagnostics are hampered by flaky telemetry, and firmware updates become risky. In technical terms, we’re talking about weak fault tolerance in the control firmware, inadequate isolation in the DC bus, and limited redundancy for essential subsystems like cooling fans and contactors. I’ve had to explain to fleet managers why a simple sensor drift can cascade into a site-wide outage — and yes, that frustration is contagious. These weak points are where procurement and testing need to be far more rigorous.
New Principles and What to Build Next
Real-world Impact
Looking forward, I favor design rules that address the specific failure modes above. A 200kw ev charger like the modular units now emerging should combine redundant power paths, active thermal monitoring, and over-the-air rollback for firmware. In practice, that means splitting the DC bus across parallel power modules, adding independent thermal sensors at heat-critical points, and using signed firmware images so a bad update can be undone automatically. These are engineering choices — not marketing points — and they change maintenance budgets and uptime statistics.
On the software side, decentralizing control functions into edge computing nodes reduces single points of failure. If one control module goes offline, the others can keep charging sessions alive while reporting fine-grained diagnostics. That kind of architecture raises complexity initially — yes — but it saves hours of site visits later. I’ve run pilot tests where redundant controllers cut mean time to recovery by more than half—funny how that works, right? In short: modular hardware, layered software, and realistic thermal margins make the biggest difference.
When you evaluate systems, focus on measurable metrics: uptime under realistic ambient conditions, mean time to recovery (MTTR) with and without remote intervention, and the granularity of telemetry (can you see cell-level, module-level, and system-level faults?). Those three metrics will tell you more than glossy brochures. Finally, if you want a vendor that understands these trade-offs, consider how they document failure modes and field-service procedures — then ask for real-world logs. For a practical reference and product detail, see Luobisnen.