
Introduction: Why this matters—now
Have you ever stood in front of a control cabinet and wondered which controller will actually hold up under real use? I have—many times—and each situation taught me something different about trade-offs. In recent projects I tracked failure rates and performance drops across dozens of units; the numbers were telling: even small inefficiencies multiply into lost uptime and higher operating costs. A good motor controller sits at the heart of that problem and its solution (we can’t ignore the day-to-day reality). So what should you ask before you commit—especially when budgets and safety are on the line?
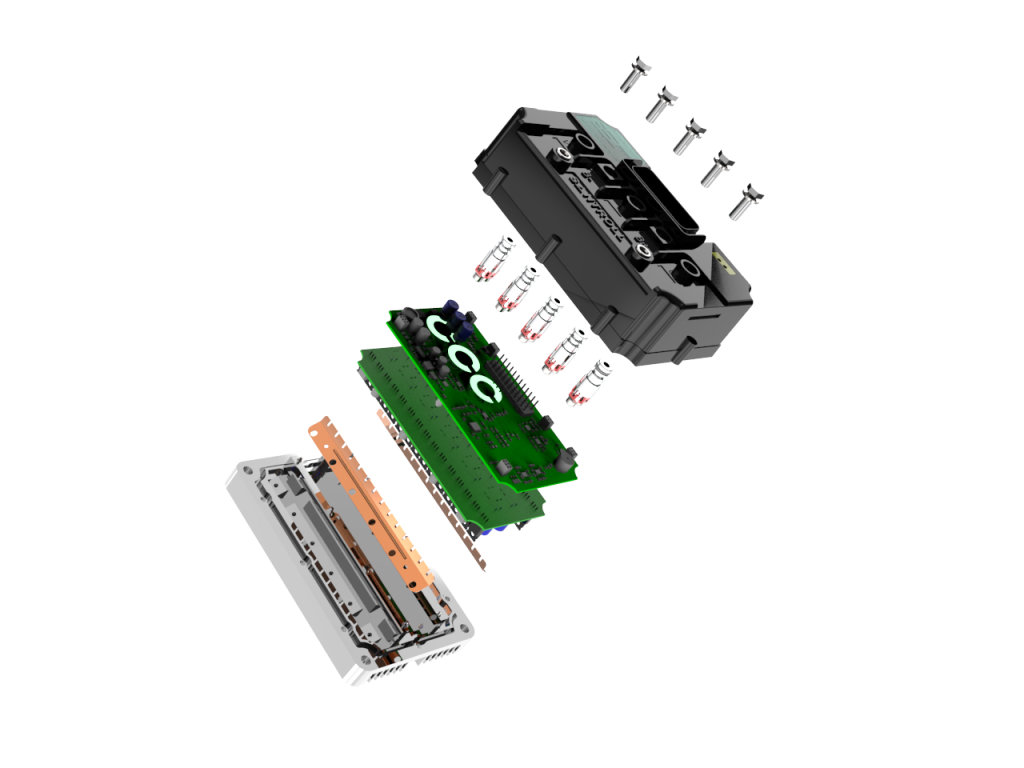
I write this as someone who has swapped controllers at 2 a.m., dialed in parameters on noisy shop floors, and argued with vendors over spec sheets. My aim here is polite and practical: to lay out the questions that reveal real capability, not glossy marketing. I’ll be frank about trade-offs. You’ll get direct comparisons, plain language on technical points, and a few hard-won preferences from my bench notes. Let us proceed to examine what really separates choices in the field—so you don’t have to learn the hard way.
Part 2 — Where traditional designs fall short (and why it matters)
electric motor solutions often promise robust performance, but many legacy approaches still rely on assumptions that break down in modern use. I’ve seen classic voltage-driven schemes struggle when loads vary rapidly. The result: poor torque control, overheating, and frequent trips. When designers skimp on adaptive feedback or lean too heavily on open-loop methods, you get unexpected downtime. Technically speaking, failures often trace back to insufficient attention to PWM modulation and inadequate handling of torque ripple. Look, it’s simpler than you think—if you focus on the wrong metric, you miss the one that matters (efficiency under dynamic load).
In practice, three common flaws keep reappearing. First, controllers built around crude sensorless control assumptions lose performance at low speeds and during direction reversals. Second, many designs use undersized power converters that heat up under peak torque, shortening lifecycle. Third, the control algorithms themselves—if not designed for field-oriented control—produce suboptimal torque per amp. These are not academic complaints; they are reasons machines stop producing. I’ve personally debugged systems where replacing the controller algorithm alone improved throughput by double digits—seriously, measurable gains that pay back quickly. — and yes, that matters.
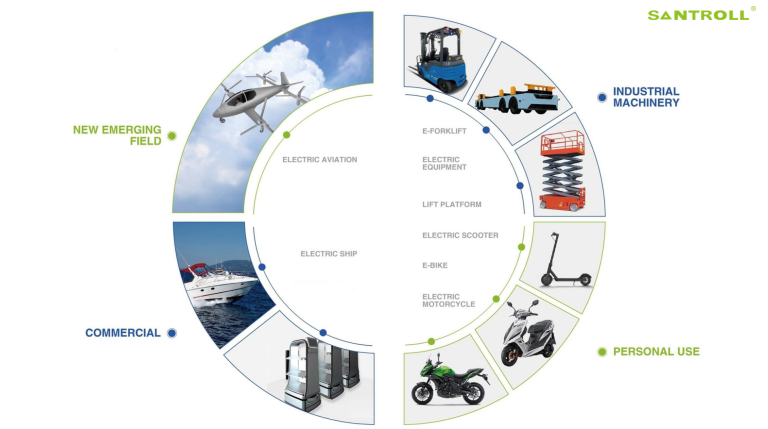
Why do users keep getting surprised?
Part of the problem is expectation management. Operators expect plug-and-play. Engineers expect predictable behavior. Neither expectation matches reality if the controller was specified from a spreadsheet rather than from measured field conditions. I recommend testing with representative loads, collecting telemetrics, and validating on the real machine. That reveals hidden friction points—resonances, transient overcurrents, or sensor noise—that specs usually hide.
Part 3 — Looking ahead: principles and practical steps for better controllers
Now let us pivot to what I think will matter going forward. I prefer principles that translate into measurable outcomes. For instance, modular control architectures that separates the power stage, the control firmware, and the communications layer make upgrades less painful. More importantly, adopting advanced field-oriented control techniques and better thermal design reduces losses and extends service intervals. In projects I advised, moving to controllers with improved thermal headroom and real-time current limiting cut maintenance windows significantly. Consider the role of digital signal processors and improved sensor fusion—these provide cleaner phase estimation and faster torque response.
Practical example: integrating a modern bldc motor controller with adaptive tuning reduced tuning cycles on a production line from three days to a few hours. That saved labor and improved yield—funny how that works, right? The key is combining robust hardware (adequate heat sinking, quality power converters) with smart software (closed-loop speed and torque control, anti-windup strategies). Also, keep communications simple but secure—fast telemetry helps you spot trends before they become failures.
What’s Next: Implementation checklist
To move from theory to practice, I recommend a short roadmap: prototype with one machine, log the key metrics (efficiency, torque variance, temperature), iterate firmware, then scale. Don’t underestimate commissioning time. Also—document your settings. You will thank me later when a technician needs to restore a known-good configuration.
Closing: How to evaluate and choose confidently
Weighing options is never purely technical; it’s also about risk and support. Based on my hands-on work, I offer three practical evaluation metrics you can use today:
1) Dynamic Efficiency: Measure efficiency not just at steady speed but across acceleration and deceleration cycles. This exposes real energy use under production conditions.
2) Thermal Margin: Check the controller’s headroom at peak torque. If the heatsink runs close to limit during normal operation, expect shortened life.
3) Control Robustness: Verify behavior in low-speed, reverse, and sudden-load-change scenarios. Sensorless methods should be validated against a real encoder where possible.
These metrics cut through marketing and highlight what I care about in the field: uptime, predictable behavior, and reasonable service intervals. I’ve seen the difference they make—so I trust them. If you run a pilot with these checks in place, you’ll reduce surprises and make smarter capital choices.
For vendors and integrators I respect, consistent data and clear commissioning support remain decisive factors. If you want a dependable partner in this space, consider checking offerings from Santroll.